Pandas for Materials Data Processing
Contents
Why Pandas
Most researchers manually merge, filter, and plot experimental data in Excel -- error-prone and time-consuming. Pandas handles all of this with a few lines of code.
import pandas as pd
import numpy as np
import matplotlib.pyplot as plt
The Pandas Workflow
Reading Experimental Data
df = pd.read_excel("mechanical_tests.xlsx", sheet_name="Sheet1")
df = pd.read_csv("force_curves.csv")

# Merge multiple files
import glob
files = glob.glob("data/*.csv")
dfs = [pd.read_csv(f) for f in files]
df_all = pd.concat(dfs, ignore_index=True)
Data Cleaning
df = df.dropna(how="all")  # Remove fully empty rows
df = df.rename(columns={"fiber_diameter_nm": "diameter", "youngs_modulus_GPa": "modulus"})

# Remove outliers (3-sigma)
for col in ["modulus", "diameter"]:
    mean, std = df[col].mean(), df[col].std()
    df = df[(df[col] > mean - 3*std) & (df[col] < mean + 3*std)]
Group Statistics
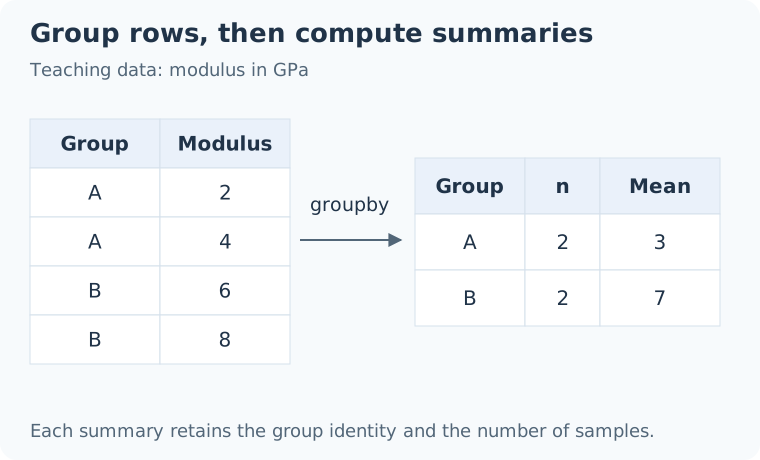
Grouping the four teaching measurements by condition gives means of 3 GPa for A and 7 GPa for B, with two samples in each group. Keeping the sample count beside the mean helps readers interpret each summary.
summary = df.groupby("treatment").agg({
    "modulus": ["mean", "std", "count"],
    "diameter": ["mean", "std"],
}).round(2)
Visualization
fig, axes = plt.subplots(2, 2, figsize=(12, 10))
df.boxplot(column="modulus", by="treatment", ax=axes[0,0])
axes[0,1].scatter(df["diameter"], df["modulus"], alpha=0.6)
corr = df.select_dtypes(include=np.number).corr()
axes[1,0].imshow(corr, cmap="RdBu_r", vmin=-1, vmax=1)
plt.tight_layout()
Export Results
summary.to_csv("mechanical_summary.csv")
df.to_csv("cleaned_data.csv", index=False)
with pd.ExcelWriter("results.xlsx") as writer:
    df.to_excel(writer, sheet_name="Raw Data")
    summary.to_excel(writer, sheet_name="Summary")
Quick Troubleshooting
| Problem | Fix |
|---|---|
| Encoding error | pd.read_csv("file.csv", encoding="utf-8") or "gbk" |
| Large file slow | Specify dtype or use chunksize |
| Date format wrong | pd.to_datetime(df["date"], format="%Y-%m-%d") |
References
- McKinney, W. (2010). Data Structures for Statistical Computing in Python. Proc. SciPy, 56-61.
- pandas.pydata.org - Pandas documentation.
- McKinney, W. (2012). Python for Data Analysis. O'Reilly Media.
Advanced Data Operations
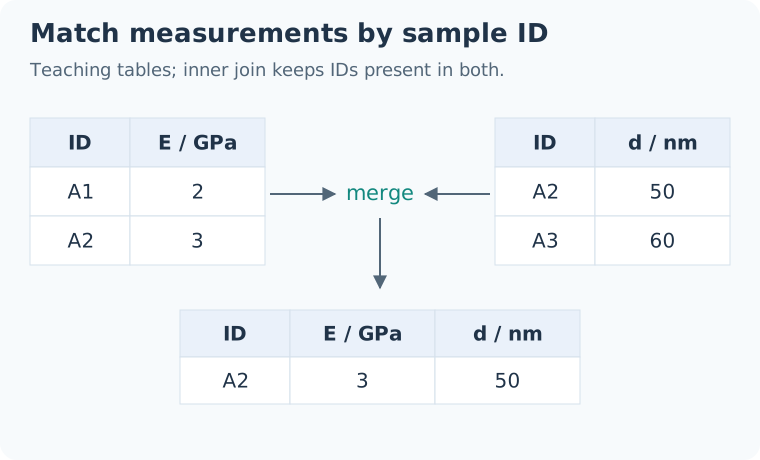
An inner join on sample ID connects the mechanics and morphology tables. Only A2 appears in both teaching tables, so the resulting row contains its modulus of 3 GPa and diameter of 50 nm.
Merging data from multiple sources is a common task in materials research. Suppose you have mechanical test results in one CSV file and fiber morphology measurements from SEM analysis in another. Pandas merge function allows you to combine these datasets on a common key such as sample ID:
mechanics = pd.read_csv("mechanical_data.csv")
morphology = pd.read_csv("sem_fiber_morphology.csv")
combined = pd.merge(mechanics, morphology, on="sample_id", how="inner")
For time-dependent measurements common in biomaterials research (degradation studies, creep tests), the rolling window functions provide smoothed trends:
df["stress_smooth"] = df["stress"].rolling(window=5, center=True).mean()
When dealing with multiple experimental conditions, the groupby transform method allows you to normalize data within each group without losing the original structure. This is particularly useful for comparing relative changes across treatments with different baseline values:
df["normalized_modulus"] = df.groupby("treatment")["modulus_GPa"].transform(lambda x: x / x.mean())